💡 The features demonstrated in this post require the latest copy of Oracle SQLcl.
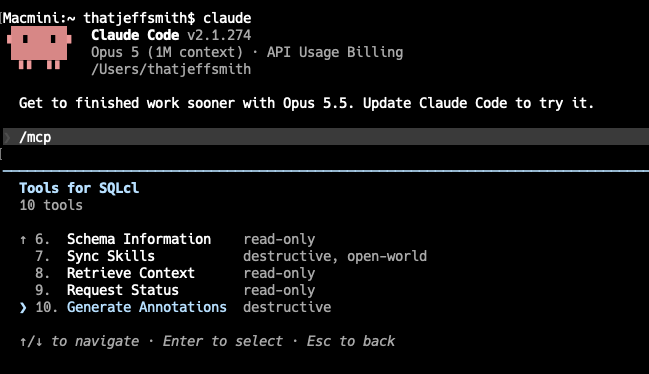
One of the reasons I enjoy Claude Code is the CLI makes it really easy to inspect MCP servers, their tools, and said tools’ descriptions.
I can simply /mcp, and then click into SQLcl, and see that we have 10 tools now.
2 New MCP Tools
- Retrieve Context
- Generate Annotations
This post is about Generate Annotations, and then another look at Schema Information. Retrieve Context will get covered in a separate post.
Getting help with our data – annotations and NL2SQL
AI Enrichment is the notion that our database schema isn’t ‘self-documenting.’ The table or column names are often confusing or just … junk. The LLM can guess how to find our data, or we can literally tell it – via enhanced metadata we call, ‘annotations.’
With this better information on hand about our database, your LLM is much more likely to get the SQL it’s generating ‘correct’ if it can understand the data model.
The main requirement for AI Schema Enrichment’s annotations feature is that our ANNOTATIONS PL/SQL API has been installed. This can be done either via SQLcl or our SQL Developer VS code extension. This enables annotations for your database objects, regardless of the database version (26ai is not required).
Checking status/installing Annotations Package
‘annotation install’ in SQLcl 26.3 –
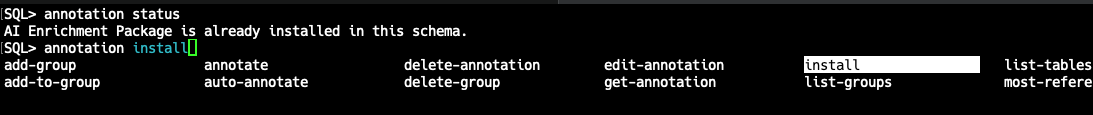
Or in SQL Developer, simply open the AI Enrichment Dashboard. SQLDev will prompt you to install or upgrade this package as necessary.
My Data
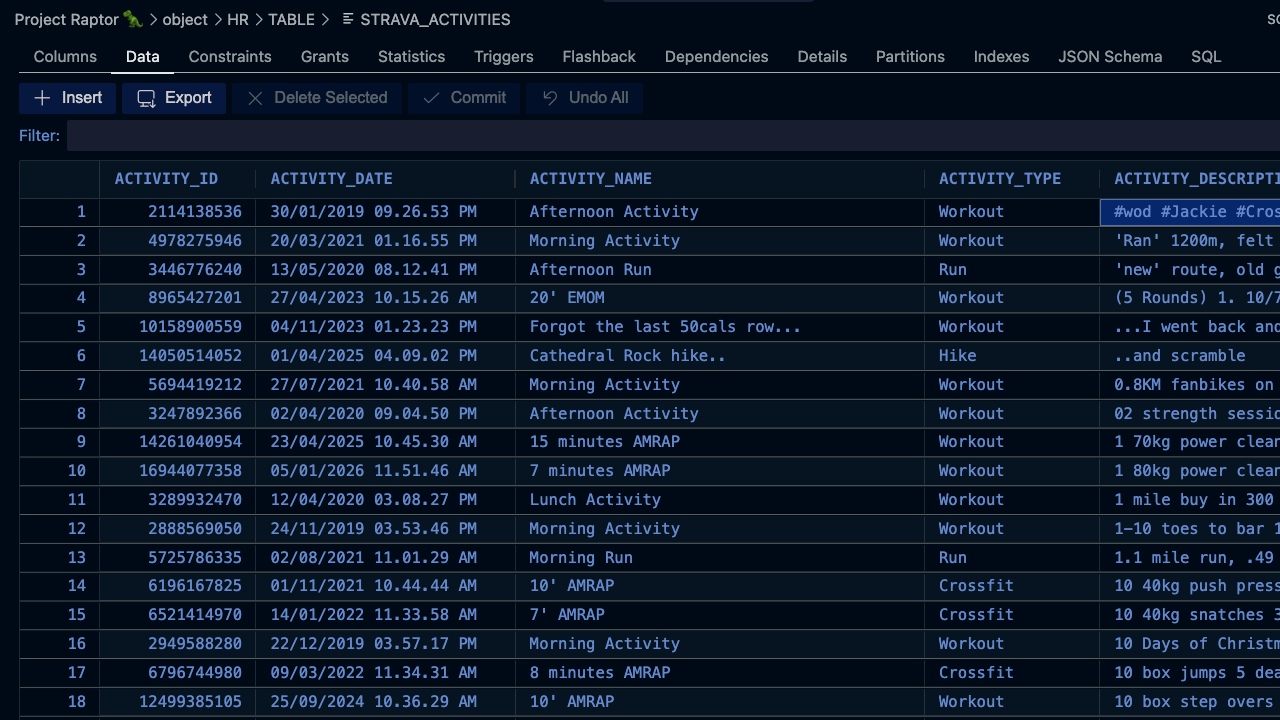
Once this has been sorted, I should be able to prompt my agent to help me ‘describe’ my table. The table in question – STRAVA_ACTIVITIES. Which looks like this:
Kicking off the Chat
Let’s prompt my agent to inspect and then start working on suggested annotations…
✻ Worked for 57s · done 10:20 AM

❯ inspect the STRAVA_ACTIVITIES table, profile the data, and use the generate annotations MCP tool, starting in preview mode, to describe the table and it's column. The column descriptions should include sample values for the most frequently filtered columns like ACTIVITY_TYPE and ACTIVITY_NAME. For the metrics columns, annotate so its clear what the unit of measurement it so the agent doesn't have to guess going forward. distance is meters and time/duration is seconds. Ask me if you need help.  And I have one annotation i want you to use - the ACTIVITY_EMBEDDING was computed using ALL_MINILM_L12_V2 sentence transformer and is computed from the concatenatation of the ACTIVITY_NAME, ACTIVITY_DESCRIPTION, and AVERAGE_HEART_RATE columns. This can be useful for doing Vector Searches on this table involving those columns. If you want to do a                                                                                                                                             search the embeddding model is loaded into the database or the agent could construct the vector on its own knowing it's ALL_MINILM_L12_V12 sentence transformer. Example query -
    SELECT
    activity_date,
    activity_name,
    activity_type,
    activity_description,
    average_heart_rate,
    calories,
    ROUND(elapsed_time_2/60, 1) as duration_min,
    relative_effort_2,
    perceived_exertion,
    VECTOR_DISTANCE(
        activity_embedding,
        VECTOR_EMBEDDING(ALL_MINILM_L12_V2 USING 'tough intense cardio under 30 minutes high heart rate no equipment needed' AS data),
        COSINE
    ) as distance
FROM strava_activities
WHERE activity_embedding IS NOT NULL
  AND elapsed_time_2 BETWEEN 600 AND 1800
ORDER BY distance ASC
FETCH FIRST 8 ROWS ONLY
…and it’s work followed along a pretty recognizable pattern. It started querying the table building a profile on the data. To get those ‘ranges’ I asked for. What would have been interesting, if i had reminded it to check the column stats as the optimizer already records the HI and LOW values 🤦
If you have a serious table, not ~1500 records, but millions or billions or more, you need to think about what you’re asking for, and if it is worth the cost!

And a summary of the work it did –
⏺ Annotating STRAVA_ACTIVITIES for AI agents

  Goal: give HR.STRAVA_ACTIVITIES metadata detailed enough that an AI agent can write correct SQL against it without guessing units, valid values or column quirks.

  1. Connect and inspect

  - Connected to Project Raptor 🦖 (Oracle Database 23.26.2) through the SQLcl MCP server.
  - Pulled the table's structure with schema_information, filtered to STRAVA_ACTIVITIES. It has 74 columns and 1,452 rows, and includes a 384-dimension ACTIVITY_EMBEDDING
    vector column.
  - Confirmed that the embedding model ALL_MINILM_L12_V2 (ONNX format) is loaded in the database.

  2. Profile the data

  Ran profiling queries on every column: non-null counts, minimum, maximum, median, distinct counts, and the most frequent values for the columns agents filter on most.

  Profiling turned up several things an agent couldn't have known from the column names alone:
  - ACTIVITY_DATE is stored in UTC, not local time. Sunrise shows as about 11:20 and "Morning" activities start between 11:00 and 15:00.
  - The older text column MAX_HEART_RATE is more complete than the number column MAX_HEART_RATE_2 (1,170 rows vs 675). ELAPSED_TIME_2 is empty on 10 rows where the text
    ELAPSED_TIME has a value.
  - The text DISTANCE column is in kilometers, but some Rowing rows hold meters. DISTANCE_2 is consistently in meters.
  - Weather data covers only 124 activities, all from June 2023 onward.
  - MEDIA can hold several file paths separated by |.
  - ACTIVITY_NAME has variants that differ only by a trailing space, such as 'Saturday Endurance '.
  - Eight columns always hold the same value where populated, so they're useless for filtering: COMMUTE_2, FLAGGED, WITH_PET, WITH_KID, CARBON_SAVED,
    PREFER_PERCEIVED_EXERTION, FROM_UPLOAD and ATHLETE_WEIGHT.

  3. Write the annotations

  Wrote one DESCRIPTION annotation for the table and one for each of the 74 columns.

  - The table description summarizes the units used throughout: distance and elevation in meters, time in seconds, speed in m/s, temperature in °C, energy in kcal, work in
    joules and power in watts. It also points out the older duplicate columns (the pairs where one has a _2 suffix) and notes which of each pair is more complete.
  - Each column description says what the column means and what unit it's in, gives usage tips where they help (conversions, NVL fallbacks, time-zone conversion) and ends with
    a VALUES: section based on the profiling:
    - For ACTIVITY_TYPE, the complete list of values with counts.
    - For ACTIVITY_NAME, the 20 most frequent values with counts.
    - For the metric columns, the range, median and number of populated rows.
    - For the flag and code columns, the values actually present.
  - The ACTIVITY_EMBEDDING description explains:
    - It was built from ACTIVITY_NAME, ACTIVITY_DESCRIPTION and AVERAGE_HEART_RATE with the ALL_MINILM_L12_V2 model.
    - To search it, embed the search text in the query with VECTOR_EMBEDDING, or build the vector yourself with the same model.
    - It includes a complete example query using COSINE distance.
    - It warns that the model handles negation poorly: "not fun" matches close to "fun".
  - Columns whose meaning isn't documented (WEATHER_CONDITION, PRECIPITATION_TYPE, INTENSITY and RECOVERY) are labeled low or moderate confidence and tell agents not to guess
    what the codes mean.

  4. Preview, review and save

  - Ran the SQLcl MCP annotation_generate tool in PREVIEW mode, and it accepted all 75 annotations.
  - After review, ran the same tool in PERSIST mode. It stored all 75 in the database's METADATA_ANNOTATIONS repository.

  5. Verify

  Ran schema_information again, filtered to STRAVA_ACTIVITIES. It returned the table description and all 74 column descriptions, each with its VALUES: section.

  An agent that asks about this table now gets the meanings, units, valid values and known data problems in a single call.

✻ Brewed for 15s · done 3:30 PM
What this looks like in the database, using our GUI
I know reading/scanning CLI / terminal output isn’t super exciting, so let’s ‘get a picture.’
In SQL Developer, in the connection tree you’ll find both an AI Enrichment Dashboard and an object browser. If I navigate directly to the STRAVA_ACTIVITIES table, I can see both the table and column level annotations.

Now that my table is annotated, let’s try working with it
I’ve started a new session, discounting whatever agent memory might be in play, let’s ask it to go into my db, get what it can from my table, and help me find some ‘happy workouts.’
Before I list the chat transcript, some things worth calling out –
Instead of bringing back the entire SCHEMA’s worth of metadata, DDL, and annotations, we limited the context window to the single table –

Managing tokens/context is important – your agent has limited memory and context helps but too much doesn’t help, and it will incur more LLM costs ($$$!)
Before running the vector similarity search, it checked to make sure the transformer (ONNX) model was available – smart!
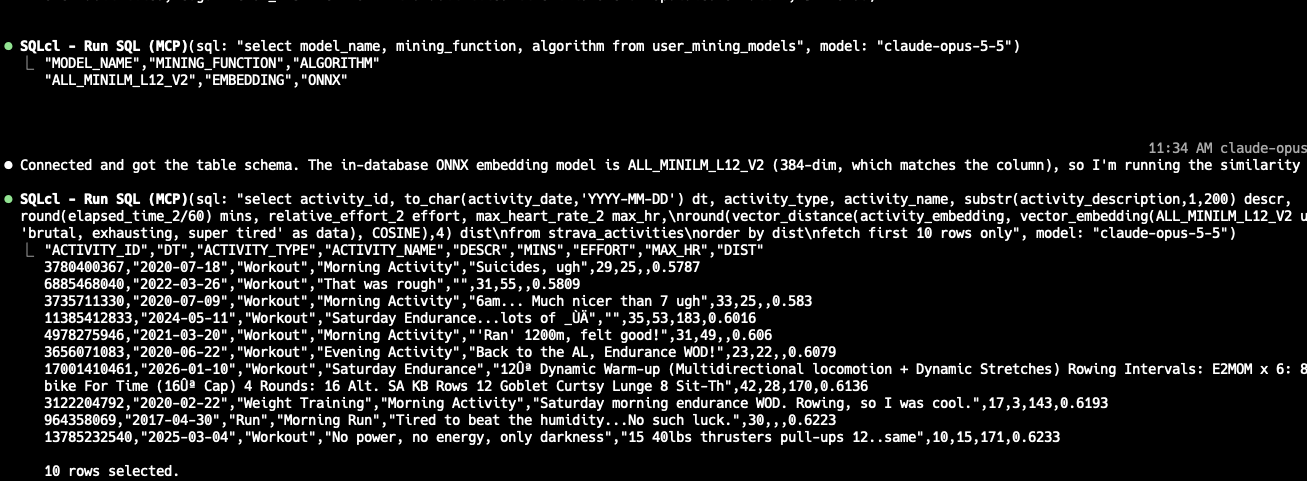
For best results you need to understand the ability of the embedding model to differentiate ‘feelings’, nuance, and of course my biggest issue – SARCASM. When I say ‘nice’ that very often means the exact opposite. That will make similarity searches more difficult.
The agent is ‘smart’ though and discovered this, several times when analyzing the query results.
After the summary, I’ll dump the last bit of chat showing the AI Vector Similarity search questions.
Summary
Your schema doesn’t explain itself, and your agent will guess if you let it. With SQLcl 26.3 and the Generate Annotations MCP tool, you can have the agent do the tedious part: profile the data, then draft descriptions for the table and every column.
Takeaways:
- Install the AI Enrichment package first. Run
annotation installin SQLcl, or open the AI Enrichment Dashboard in SQL Developer. You don’t need 26ai. - Tell the agent what you already know. Units, which columns people filter on, how the embedding was built. It’ll figure out a lot on its own, but it can’t know that DISTANCE_2 is in meters unless the data proves it or you tell it.
- Always preview, then read before you persist. The profiling caught things I didn’t know about my own data: UTC dates, meters hiding in a kilometers column, and a “legacy” column that was more complete than its replacement. It can also be confidently wrong. You’re the one who approves it.
- Keep what you pull back small. Use the Schema Information tool’s filter so the agent gets one table’s metadata, not the whole schema. Tokens cost money, and too much context doesn’t help.
- Know what your embedding model can’t do. ALL_MINILM_L12_V2 is great at matching topics and bad at “not fun” (and at my sarcasm). Put that warning in the annotation, and combine vector search with real metrics like relative effort or heart rate when feelings aren’t enough.
Annotations are for the long haul. Write them once and every agent, tool, and person who touches the table afterward benefits. That includes SQL Developer, where they show up right in the object browser.
Next up: the other new tool, Retrieve Context.
My NL2SQL chat with AI Vector Search – benefitting from our new annotations
❯ connect to my Project Raptor  database, get the schema information for my STRAVA_ACTIVITIES table, and then let's do a vector similarity search, i want to find workout activities that resemble 'brutal, exhausting, super tired' exercises. when using the schema-metadata tool, be sure to use the FILTER tool attribute to only get back the metadata for that table

  Called SQLcl 4 times (ctrl+o to expand)

⏺ Connected and got the table schema. The in-database ONNX embedding model is ALL_MINILM_L12_V2 (384-dim, which matches the column), so I'm running the similarity search now.

  Called SQLcl (ctrl+o to expand)

⏺ I connected to Project Raptor , pulled the metadata for STRAVA_ACTIVITIES only (filter = 'STRAVA_ACTIVITIES'), and ran the similarity search.

  Connection: Oracle 23.26.2, open in read-write mode, language set to American, autocommit off. I only ran queries, so there's nothing to commit.

  The table (schema HR, 1,452 rows):
  - ACTIVITY_EMBEDDING is a 384-dimension vector built from the activity name and description.
  - The embedding model ALL_MINILM_L12_V2 (ONNX format) is loaded in the database, so the search text was turned into a vector there with VECTOR_EMBEDDING.
  - Some older columns store numbers as text. I used the number versions: ELAPSED_TIME_2, RELATIVE_EFFORT_2 and MAX_HEART_RATE_2.

  Top 10 closest matches for 'brutal, exhausting, super tired' (cosine distance; lower means closer):
...
I’ve pasted in a picture of the response here so it’s easier to read…

What stands out:
  - The strongest matches are the ones where you wrote how it felt: "Suicides, ugh," "That was rough," "No power, no energy, only darkness," and "Tired to beat the humidity."
  - The distances are fairly high (0.58–0.62), so these are loose matches. Most descriptions are short or empty, which gives the model little to work with, and a few results
    match on "Endurance" rather than on suffering. #5 ("felt good!") is a clear false positive.
  - The text doesn't line up with the effort data. Most of these have a modest Strava relative effort (15–55), while the table goes up to 293.

  If you want the workouts that were actually brutal, I can combine the two in one query: rank by vector similarity but keep only rows with high RELATIVE_EFFORT_2,
  MAX_HEART_RATE_2 or PERCEIVED_EXERTION.

✻ Churned for 41s · done 11:34 AM

❯ let's go the other way, let's look for workouts where i was very happy, content, pleasant, enjoyable

  Called SQLcl (ctrl+o to expand)

⏺ These matches are much weaker than the "brutal" ones, and the top result is the opposite of what you asked for.

  Top 10 closest matches for 'very happy, content, pleasant, enjoyable' (cosine distance; lower means closer):
...
again, pasting image of the output so it’s easier to read

What stands out:
  - The top hit is "Not fun." This embedding model is poor at handling negation. It sees that "fun" is close to "enjoyable" and mostly ignores the "not." Semantic search has
    this weakness in general: it can tell what topic a note is about, but it often gets whether the feeling is positive or negative wrong.
  - These are weak matches overall. The distances are 0.77–0.82, compared with 0.58–0.62 for the "brutal" search. You write about suffering much more often and more vividly
    than about enjoying yourself. The happy notes are short: "fun," "awesome breeze," "amazing weather."
  - The good matches:
    - "Amazing weather" on an evening ride
    - "Fun with cardio"
    - The breeze runs (#4 and #5)
    - "Felt good!" (#6)
    - "Rowing, running, biking...fun" and "EMOM fun"
  - The happy workouts tended to be easy. Several have a relative effort in the single digits (2, 4, 7), and the top "positive" match is a 71-minute ride. You apparently enjoy
    the workouts that don't wreck you. The exception is #3, "Fun with cardio," with effort 61 and max HR 183.
  - Also wrong: #7 ("Foot felt a bit bummy") matched only because it's short text about how you felt.

  I can rerun this with obvious negations like "not fun" or "no fun" filtered out. I could also add the weather columns to test whether the happy workouts really do cluster on
  nice days.

✻ Baked for 15s · done 11:36 AM
1 Comment
It is helpful that annotations can be generated with the help of AI. However, as you have explained earlier, annotations, if well defined, are even more helpful to AI to be able to generate the correct SQL for returning the correct results. In the past developers used tooling such as Oracle Designer or SQL Developer Datamodeler, and the repositories of these tools contained (if used correctly) exactly everything we need in annotations. I am currently testing how to efficiently extract such information into annotations with help of sqlcl mcp, which should result in more sofisticated annotations.